Mentions
Conversations linking to GitHub, newest first. Times are UTC.
Mentions by source
X
Bluesky
Hacker News
Lobsters
V2EX
Qiita
DEV
Mailwal
Zenn
Mastodon
Latest posts
ComfyUI Tutorial: PIKA H3 + MiniMax H3 Singularity V2 + NVIDIA Regenerative 2K Upscaling KIJAI LORA (With 6GB of VRAM) Hello everyone today I am showing you a new ComfyUI workflow that combines MiniMax H3 Singularity V2 combined with the Pika H3 LoRA to generate videos at approximately 0.6 MP with only 6 steps. Then, using the Ultimate MiniMax H3 Upscale node and Kijai's Regenerative 2K LoRA at a lower weight, the video is progressively enhanced with additional LoRAs to improve details, textures, and overall quality. My test results: - Initial generation: 0.6MP - Sampling steps: 6 - Total generation + upscaling time: ~1 hour - Final resolution: Full HD (1920×1080) The interesting part is that instead of generating directly at high resolution, we generate at a much lower resolution and let the regenerative upscaling process recover and enhance the details. I've included all the required LoRA and custom node links with the workflow. Let me know what you think, especially if you've tested this new regenerative upscaling approach! Required LoRAs and Models 1. Open Regenerate 2K LoRA (Kijai): huggingface.co 2. LMS LoRA: huggingface.co 3. Pika H3 LoRA: huggingface.co 4. Sharp Curve LoRA: huggingface.co 5. Latent H3 Upscaling Model: huggingface.co Custom Nodes to Install 1. Ultimate MiniMax H3 Upscale: cbbaudio-2025/ComfyUI-MH3-UltimateUpscale Workflow Link drive.google.com civitai.com
Have you ever felt like your running out of time and therefore inclined to take even more risk? It seems counter-intuitive and it seems to be a common line of thought! Check out: XibalbaTechSol/xibalba-shield
ComfyUI Tutorial: PIKA H3 + MiniMax H3 Singularity V2 + NVIDIA Regenerative 2K Upscaling KIJAI LORA (With 6GB of VRAM) Hello everyone today I am showing you a new ComfyUI workflow that combines MiniMax H3 Singularity V2 combined with the Pika H3 LoRA to generate videos at approximately 0.6 MP with only 6 steps. Then, using the Ultimate MiniMax H3 Upscale node and Kijai's Regenerative 2K LoRA at a lower weight, the video is progressively enhanced with additional LoRAs to improve details, textures, and overall quality. My test results: - Initial generation: 0.6MP - Sampling steps: 6 - Total generation + upscaling time: ~1 hour - Final resolution: Full HD (1920×1080) The interesting part is that instead of generating directly at high resolution, we generate at a much lower resolution and let the regenerative upscaling process recover and enhance the details. I've included all the required LoRA and custom node links with the workflow. Let me know what you think, especially if you've tested this new regenerative upscaling approach! Required LoRAs and Models 1. Open Regenerate 2K LoRA (Kijai): huggingface.co 2. LMS LoRA: huggingface.co 3. Pika H3 LoRA: huggingface.co 4. Sharp Curve LoRA: huggingface.co 5. Latent H3 Upscaling Model: huggingface.co Custom Nodes to Install 1. Ultimate MiniMax H3 Upscale: cbbaudio-2025/ComfyUI-MH3-UltimateUpscale Workflow Link drive.google.com civitai.com
[OS] MeowDisplay: use your Mac from your iPhone/Android or iPad (free & open source) iPhone Duo Supported! Hi! I'm the developer of MeowDisplay, a free and open-source app that lets you use your iPhone or iPad as an additional display for your Mac. I've added support for the iPhone Duo, and its larger unfolded display should be particularly useful with MeowDisplay's Window view. Rather than squeezing an entire Mac desktop onto a phone, you can arrange individual Mac windows into multiple panes, switch between them using Stage Peek, and interact using touch, trackpad-style controls, or a keyboard. You can also mirror or extend your Mac's desktop and stream its audio. Someone recently mentioned that MeowDisplay works great on their Duo, which was encouraging! I haven't personally tested it on physical Duo hardware yet, though, and I haven't seen screenshots of it running on one. If anyone here has a Duo and wants to try it, I'd appreciate screenshots of the layouts and any feedback on how the windows, controls and resizing behave. MeowDisplay is completely free and open source, with no ads, subscriptions or accounts. You'll also need the free Mac companion app. App Store Website / Mac download Source
ComfyUI Tutorial: PIKA H3 + MiniMax H3 Singularity V2 + NVIDIA Regenerative 2K Upscaling KIJAI LORA (With 6GB of VRAM) Hello everyone today I am showing you a new ComfyUI workflow that combines MiniMax H3 Singularity V2 combined with the Pika H3 LoRA to generate videos at approximately 0.6 MP with only 6 steps. Then, using the Ultimate MiniMax H3 Upscale node and Kijai's Regenerative 2K LoRA at a lower weight, the video is progressively enhanced with additional LoRAs to improve details, textures, and overall quality. My test results: - Initial generation: 0.6MP - Sampling steps: 6 - Total generation + upscaling time: ~1 hour - Final resolution: Full HD (1920×1080) The interesting part is that instead of generating directly at high resolution, we generate at a much lower resolution and let the regenerative upscaling process recover and enhance the details. I've included all the required LoRA and custom node links with the workflow. Let me know what you think, especially if you've tested this new regenerative upscaling approach! Required LoRAs and Models 1. Open Regenerate 2K LoRA (Kijai): huggingface.co 2. LMS LoRA: huggingface.co 3. Pika H3 LoRA: huggingface.co 4. Sharp Curve LoRA: huggingface.co 5. Latent H3 Upscaling Model: huggingface.co Custom Nodes to Install 1. Ultimate MiniMax H3 Upscale: cbbaudio-2025/ComfyUI-MH3-UltimateUpscale Workflow Link drive.google.com civitai.com Video Tutorial youtu.be
Dory 让你能在 Mac 电脑上搭起一整套本地运行的 Linux 工作环境。 这套环境把 Docker、Kubernetes 与一个带图形界面的 Linux 桌面整合在一起。 项目地址为 Augani/dory 。 t.co
Art director, not a developer: I built BeeKeeper with Claude Code to see what my agents do behind my back I run a lot of Claude Code sessions at once and kept losing track of them. Which one is working, which one is waiting for me, which one quietly stopped an hour ago. So I built BeeKeeper, a pixel-art hive. Every project is a room. Every Claude Code chat and every agent is a little character that walks into its room, works with a speech bubble showing what it's doing right now, waits for me, and falls asleep when it's idle. When Claude calls a subagent, you see it step into the room. How Claude helped: I'm an art director, not a developer, so Claude Code wrote basically all of it from my direction. It's React + Vite with a small Node server that reads the session logs and agent files Claude Code already keeps in ~/.claude and your project folders. I did the art direction, rooms and characters. One thing I changed along the way: I realised most people won't pay to generate their own rooms and characters, so I spent a few more dollars building a bigger free library. It ships with 20 ready rooms and 17 characters. Drawing your own room is optional (about 10 cents with your own Gemini key). Also, the short promo video took 3 times longer than I expected. Classic. - 100% free, open source, MIT licence - Runs locally, only reads your Claude Code folders, nothing is uploaded (the only exception is if you choose to generate a custom room, then your description goes to Google's image model) - Also has tabs for your agents' records and how often you use each skill ranucho/beekeeper Happy to answer anything about how it reads the sessions.
Direct2DとDirectWriteの使い方が少しわかった。 windows.h, d2d1.h, dwrite.h を使わずにヘッダファイルを自作した(自作の意味はない。) takazin11de/my_d2d_dwrite t.co
Worth a look if you often collect web data with Python. It also describes ways past protections like Cloudflare, so use it only on permitted data and within site terms. D4Vinci/Scrapling
NSH: A Native UI Framework for iOS, Android, macOS, Windows, Linux and the Web
[For Hire] Remote Windows kernel driver development - EUR 100 for an agreed small task I maintain Windows input and virtual-device projects and am available for small custom kernel-driver tasks, remotely. EUR 100 fixed price for a scope we agree on first; PayPal or Stripe. Suitable examples would be a specific peripheral input filter, a small virtual-device prototype, or an addition to a controlled test setup. Development is AI-assisted, with final human review and finishing by me. A small implementation can be ready in a few hours once the requirements are agreed. Microsoft signing is submitted through Partner Center, subject to acceptance and processing; I cannot promise the signing step within those hours. Examples of my work: TitanCSA/Interceptor-Keyboard-Mouse TitanCSA/Vdevice Tell me the intended behavior, Windows version and device/protocol, and I'll check whether it fits the EUR 100 scope. Legitimate, authorized uses only. You can reply here with a non-sensitive brief.
[OriginOS 7] OriTweaks: Tweaks for OriginOS 7 China I’ve been running the China X200 Ultra (PD2454) rooted on OriginOS 7. I made two open-source mods for it to fix/improve things that might be useful to others. OriTweaks is a libxposed (API 102) module. You can turn each feature on or off in its app: - Instant app drawer after recents. Normally, if you swipe up right after leaving recents, the launcher ignores the swipe for about half a second. With the module, the drawer opens straight away. - Origin Island music player for more apps. Pick any app (YouTube Music is on by default) to get the island music card and the control-center player. That app’s own media notification is hidden, so you don’t get two players. - Game super resolution and frame interpolation for any game (experimental). Adds the games you choose to vivo’s lists, using vivo’s generic profiles. The game also has to be added in Game space. - 50 MP in third-party camera apps (experimental). Verified working: - PhotonCamera on the main, ultrawide and periscope (HP9) cameras; - Open Camera with its Camera2 API setting turned on. camx-fullsize is a KernelSU/Magisk module. It’s required for the 50 MP feature: - By default, vivo’s camera HAL only gives binned 12.5 MP to apps other than its own camera. This module turns on the HAL’s full-size Quad Bayer outputs and adds the remosaic sensor-mode rules. - It also exposes the hidden physical cameras to PhotonCamera and Open Camera, so the HP9 periscope shows up as its own camera. - It ships no vivo files. At every boot it patches the stock config and bind-mounts the result, so it keeps working across OriginOS 7 updates. Nothing in /vendor is modified, and uninstalling and rebooting brings back stock. - The HAL change alone isn’t enough, because most apps get the Camera2 pixel-mode rules wrong. OriTweaks fixes those requests inside the camera app. Requirements - vivo X200 Ultra, China firmware, on OriginOS 7 (Android 17). - Root (I use KernelSU) and Zygisk (NeoZygisk). - Vector-SR as the Xposed framework. It’s what I developed and tested on, and I recommend it. Other libxposed API 102 frameworks may work, but they’re untested. - Shizuku is optional. With it, the app restarts the affected apps without a soft reboot. Known limits - 200 MP on the HP9 doesn’t work. The HAL aborts, and vivo’s camera uses an offline remosaic for it. - Only tested on my phone, so use at your own risk. Links - OriTweaks: kailashrs/OriTweaks (APK under Releases) - camx-fullsize: kailashrs/camx-fullsize (flashable zip under Releases) Both are GPL-3.0. Bug reports and logs are welcome on GitHub. Each hooked app writes an oritweaks.log, and the READMEs say where to find them.
VMA Radio Lab – VMA Broadcast Hello, Based on the amazing work of CasualArcLamp with DecSAT (github.com/CasualArclamp), I continued to shape this software to become what I understand is the most complete SDR software. I renamed it to VMA Radio Lab, it is open source (as DecSAT, DecDVB-T, DecDAB,...). It features support for additional SDR devices, adds many additional digital and analog demodulators, including ATV in color with teletext support! It has measurement (audio, video, modulations) and allows to use multiple SDR devices concurrently. One can be assigned to render a live spectrum overview with a really fast refresh rate. Finally, it supports TBS DVB-S/S2/T/T2/C/C2 tuners (must be compatible with CrazyScan). This allows to control the satellite dish and/or demodulate wide-band transponders for which the SDR cannot offer high enough sample rate. Windows binaries can be downloaded and used directly. Source code can be downloaded, too. Welcome to amateur radio in 2026!
@onusoz @pidotdev wrote a switch decider that runs a small local model in-process, no API calls. you can hand it Jev as a teacher and it trains on Jev’s answers debuffjp/decidekit
tradingview adblock i blocked all their ads and the popups for time-frames you cant use and the subscribe full screen ad update blocker done go grab it if you want md3222/tradingview-de-nag
@onevcat 您好。CotEditor 这边有个 PR 需要确认一下您的意见。您前两天刚刚给该专案的与游标上下文方向有关的 zh-Hans L10n 做了修改,但这个表述是与 Apple 官方表述正好相反的。请您在我这个 PR 里面做出与此有关的裁示。我会根据您的裁示决定是否在该 PR 砍掉简体修正。 CotEditor#2188
意外とepub形式出力への要望があったので、OSS版の組版テンプレートのリポジトリにepub出力を追加してる。 dotsさんに任せてPRつくらせてる。 一発目だと、まだまだ出力が甘かったので、修正中。 techbook_starter_kit#39
@LLMADDAI I'd start with Qwen3.8-27B MLX 4-bit on one A100 and check your real tool-call chains first. The CUDA measurements in that recipe are from Sparks, so I'd want A100 results before calling it stable. github.com/ashhart/TensorFold/blob/main/docs/reci…
Custom Windows kernel driver development - EUR 100 for an agreed small scope Need a small Windows kernel driver for a peripheral, a virtual device or a test setup? I offer custom development for EUR 100, paid by PayPal or Stripe, after we agree on the exact scope. The work is AI-assisted, with final review and finishing by me. For a small, agreed task, I aim to have the implementation ready within a few hours. Microsoft signing goes through Partner Center and depends on acceptance and processing, so that timing is separate. Some of my existing projects: TitanCSA/Interceptor-Keyboard-Mouse TitanCSA/Vdevice All my tools: titanfyre/Titan-Input-Tools If you have a legitimate use case, reply with what the driver should do, your Windows version, and the device model or protocol. Please leave private details out of public comments. I'll check whether it fits the EUR 100 scope before we agree to proceed.
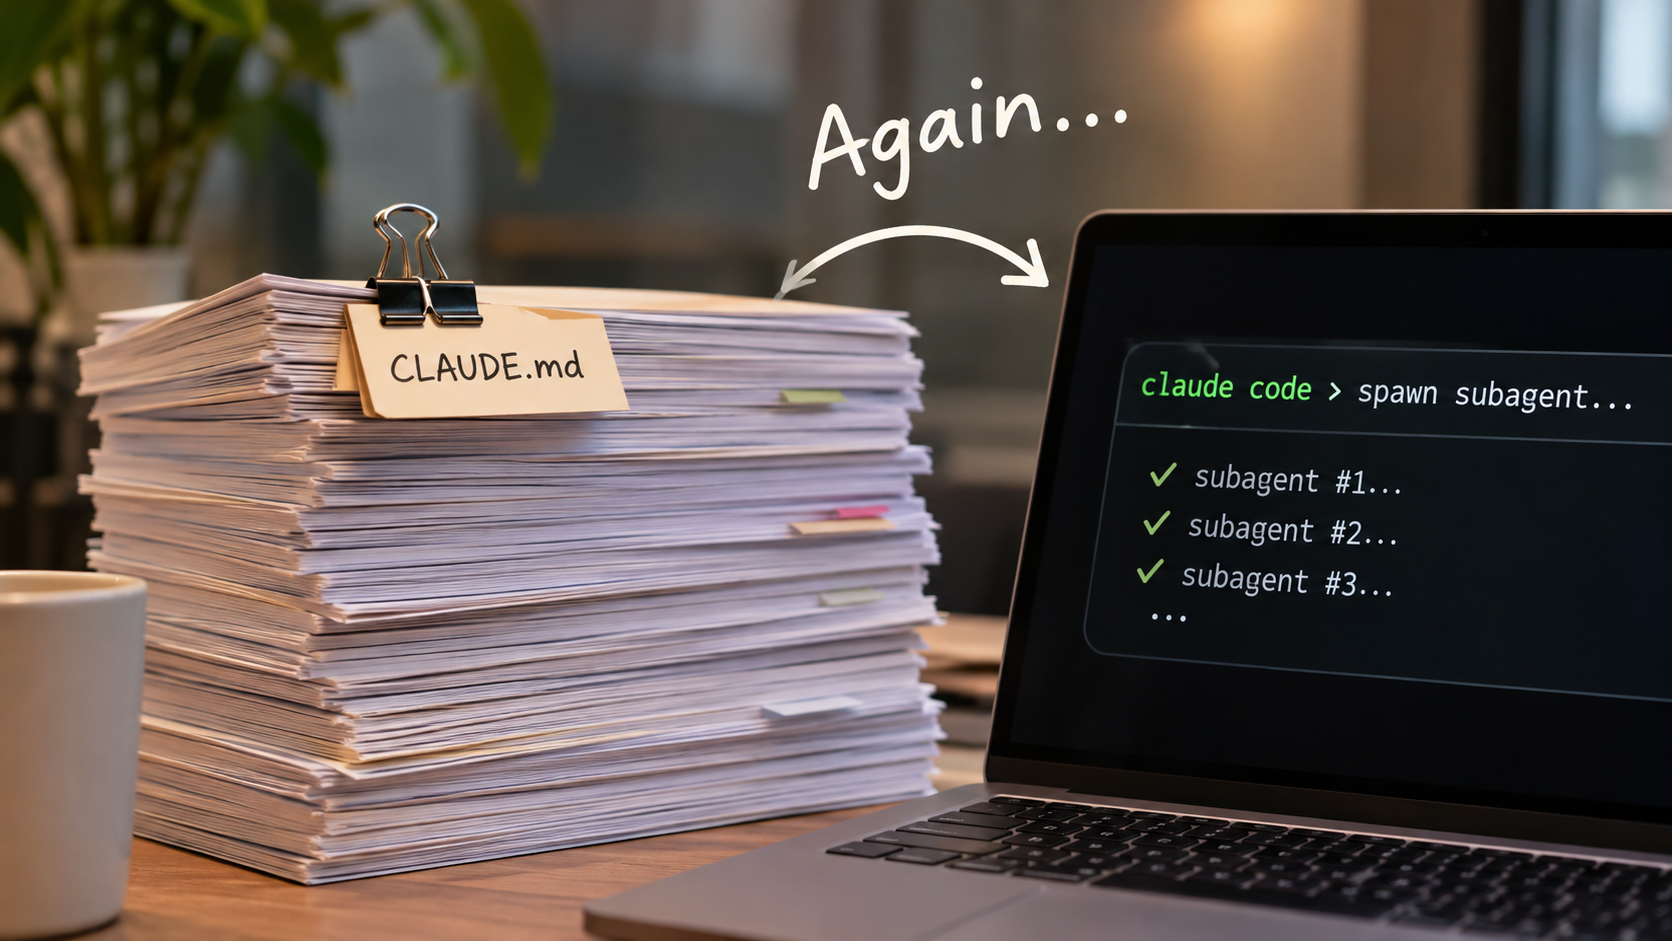
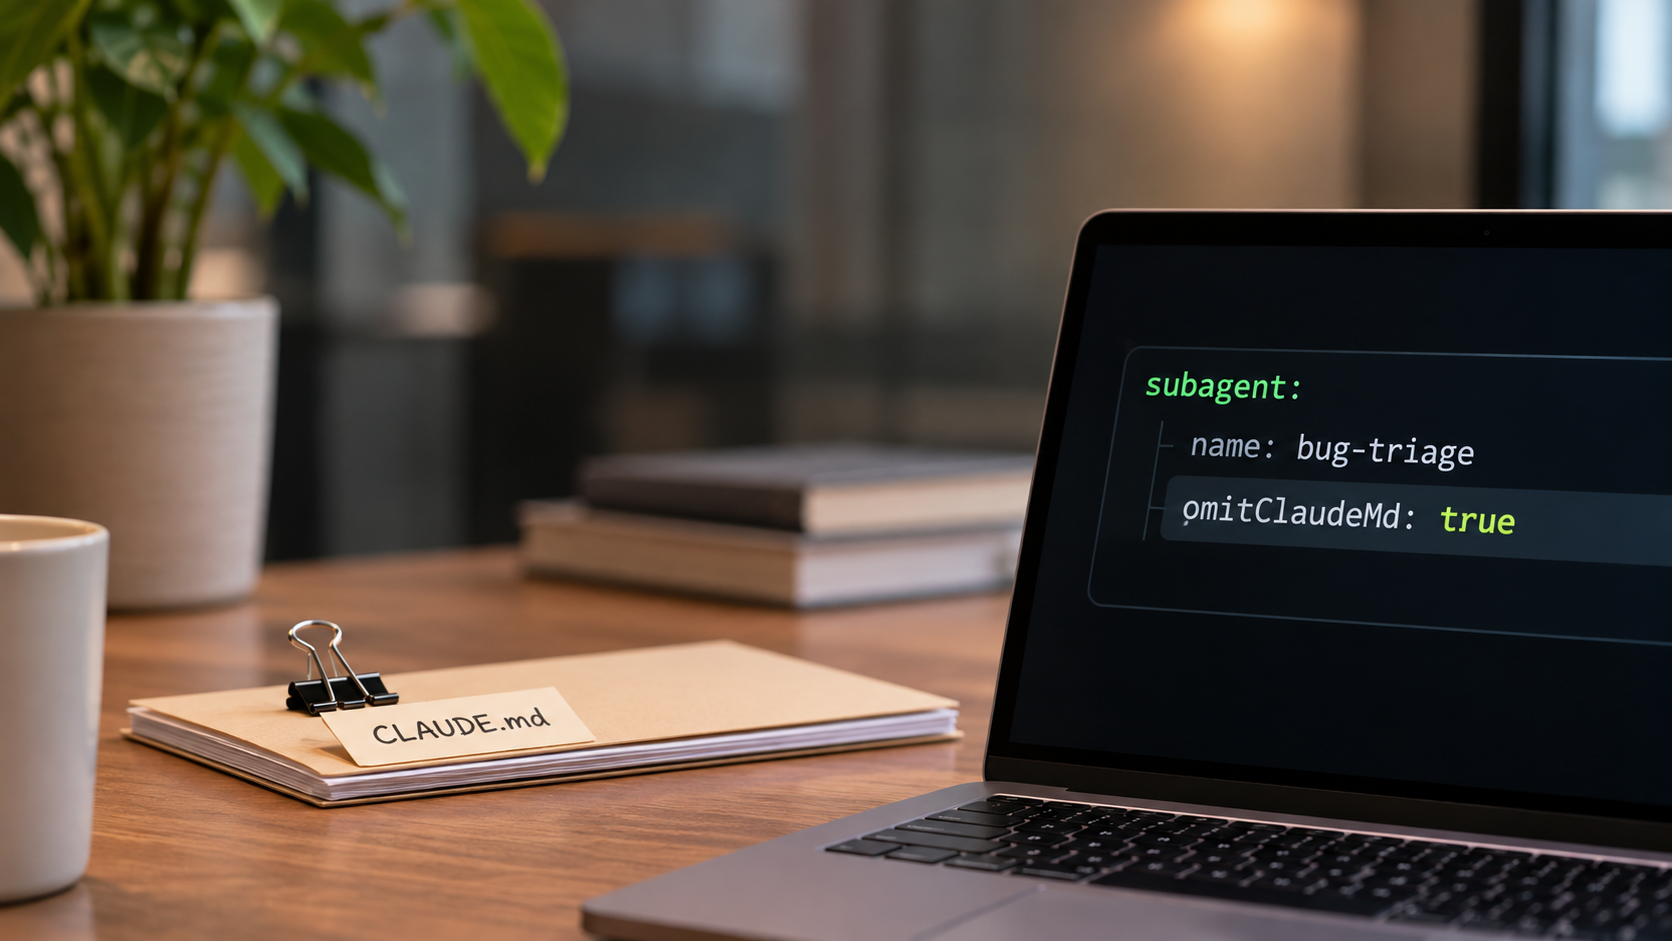
Your Claude Code subagents pay for... ...your CLAUDE.md on every turn again, and again. and again... --- Every custom subagent you spin up in Claude Code gets a copy of your CLAUDE.md before it does any work. Then it carries that copy along on every request until it finishes. If you've got a big CLAUDE.md, every subagent starts with a pile of tokens before it's even looked at your code. I went through the 722 subagent logs on my machine (September 26 to November 2). My code reviewer started at a median of 80,111 tokens on its first request. Claude Code's built-in Explore agent started at 7,578. Same machine, mostly the same repos. One gets the house rules. The other doesn't. --- Why the gap Anthropic's subagent docs are pretty clear about this: "Explore and Plan start without your CLAUDE.md files and the git status snapshot to keep research fast and inexpensive." Every other subagent, built-in or custom, loads both unless you tell it otherwise. I figured the tools might account for some of the difference. My reviewer only has four (tools: Read, Grep, Glob, Bash), so that wasn't much of an explanation. Then I looked at my CLAUDE.md. The one in the jCodeMunch repo is 1,064 lines. That's 36,931 tokens using tiktoken's cl100k count (Claude's tokenizer will give you a somewhat different number). Apparently I need to start taking my own advice. Each subagent runs its own conversation, and every request carries the conversation's context along with it. My reviewers took a median of 17 requests. 17 times 36,931 comes to about 628,000 tokens per review. Just for the house rules. The agent hasn't opened a file yet. !©2026 jCodeMunch.com Now, most of those repeated tokens bill at the cached rate. That helps, and I went through the math on that last week. But cached doesn't mean free, and on a subscription it all comes out of the same usage limits. Somebody on r/ClaudeCode described their starting context as "So ~125k before any work happens". Another reported: "It spun up 20+ agents and burned my entire 5 hour window in 15 mins". Multiply that starting context by the number of agents, and then by the requests each one makes, and the numbers start making a little more sense. Not necessarily the kind of sense you wanted, but sense nonetheless. --- Measure your own Claude Code keeps subagent transcripts alongside the parent session, in ~/.claude/projects/<project>/<session>/subagents/. Each subagent has a little .meta.json file naming its agentType, and the .jsonl transcript has the API usage block on each assistant entry, same as the main session. One caution, same as last time: Anthropic doesn't document this log format. It's fine for poking around your own sessions, but I wouldn't build anything important on it staying the same. import glob, json, os from collections import defaultdict from statistics import median root = os.path.expanduser("~/.claude/projects") first, turns, sent = defaultdict(list), defaultdict(list), defaultdict(int) for log in glob.glob(os.path.join(root, "*", "*", "subagents", "*.jsonl")): try: kind = json.load(open(log[:-6] + ".meta.json", encoding="utf-8")).get("agentType", "?") except (OSError, ValueError): kind = "?" sizes, seen = [], set() for line in open(log, encoding="utf-8"): try: m = json.loads(line).get("message") or {} except ValueError: continue u = m.get("usage") if isinstance(m, dict) else None if u and m.get("id") not in seen: seen.add(m.get("id")) sizes.append(u.get("input_tokens", 0) + u.get("cache_read_input_tokens", 0) + u.get("cache_creation_input_tokens", 0)) if sizes: first[kind].append(sizes[0]) turns[kind].append(len(sizes)) sent[kind] += sum(sizes) print(f"{'agent type':20}{'runs':>6}{'first request':>15}{'requests':>10}{'tokens sent':>16}") for kind in sorted(first, key=lambda k: -sent[k]): print(f"{kind[:19]:20}{len(first[kind]):>6}{median(first[kind]):>15,.0f}" f"{median(turns[kind]):>10.0f}{sent[kind]:>16,}") print("(first request and requests are medians per run)") python subagentfloor.py Here's mine (Claude Code 2.1.316, a few test agents trimmed off the bottom): agent type runs first request requests tokens sent reviewer 406 80,111 17 1,017,763,755 general-purpose 67 66,703 17 211,755,063 Explore 202 7,578 3 16,942,168 spokesperson 22 77,372 2 6,823,506 claude-code-guide 6 112,665 4 3,765,695 web-fetch 10 3,893 4 1,214,448 (first request and requests are medians per run) The column to look at first is "first request". That's the agent's starting floor. System prompt, CLAUDE.md, git status snapshot, tool definitions, and whatever instructions the main session handed it. Every request after that carries the same starting baggage, plus whatever the agent has picked up while working. You can also count the tokens in your own CLAUDE.md: python -c "import tiktoken; print(len(tiktoken.get_encoding('cl100k_base').encode(open('CLAUDE.md', encoding='utf-8').read())))" --- The thing I expected to matter more I went into this expecting file re-reads to be the big problem. You see people say it all the time: "the gap is re-reads, not work." Fair enough. I figured I'd measure that too, in my three busiest sessions (78, 127 and 225 subagents). Files another agent had already read accounted for 9% to 13% of all the file content read. File contents carried into later turns came to 2% to 6% of what the subagents sent. The starting context, re-sent every turn, was 52% to 69%. Well, that wasn't what I expected. Now, my agents don't spend much time crawling through the repo. I've got some tooling that changes how they find code, which I'll get to below. If your agents spend their days opening files, your numbers could look considerably different. Still, the starting floor might be worth measuring before you go chasing re-reads. It's sitting there on every request, whether the agent does anything useful or not. And it's relatively easy to fix. --- Lowering the floor First up might be omitClaudeMd: true. Put that in the frontmatter of an agent that doesn't need your project rules. Per Anthropic's docs, it starts the subagent "without the user, project, and local CLAUDE.md files in its initial context." A test runner probably doesn't need to know how you format commit messages. Neither does an agent summarizing logs. A code reviewer that's supposed to enforce those conventions? Different story. Leave the rules in place for that one, or at least give it the parts it actually needs. It might also be worth a look at what's piled up in CLAUDE.md itself. Mine is obviously overdue for some housekeeping. If a section only matters to one kind of agent, it can live in that agent's own file, and nobody else has to carry it. For looking around the repo, Claude Code already has Explore. It skips CLAUDE.md and runs read-only. A decent brief helps too. The main session already knows quite a bit about the repo. If it knows which files and functions need attention, have it pass those names along instead of making the new agent rediscover them. And if the job doesn't need a big model, Anthropic's costs page suggests model: haiku in the agent's config. !©2026 jCodeMunch.com None of this needs another tool. Just a little attention to what you're making each agent carry around. --- Where jCodeMunch fits Once you've dealt with the starting context, there's still the matter of how a cold agent finds its way around the code. Normally it searches, opens files, finds the function it wanted, and keeps all that file content in its conversation for the rest of the run. That's the part I built jCodeMunch for. A subagent only gets the tools allowed in its agent file. Add mcp__jcodemunch__* to the tools: line and it can ask for a function by name instead of opening the entire file. On our benchmark that's 94.5% fewer tokens per lookup on average than grep-and-read (15 lookups across express, fastapi and gin; method here). Run jcodemunch-mcp init --guidance and each spawned subagent also gets a condensed briefing about the repo, so it doesn't start completely cold. And here's the embarrassing part. Remember my reviewer? The one that starts at 80,111 tokens and spends 17 requests doing its job? I checked its tools: line. No jCodeMunch. Guess what I'm fixing tonight... jcodemunch.com FAQ Does a subagent see my main conversation? Not a regular one. It starts with its own context: its system prompt, CLAUDE.md (unless omitted), the git status snapshot, its tools and the brief. A fork is the exception; it inherits the conversation so far. Does omitClaudeMd drop everything? It drops the user, project and local CLAUDE.md files. Managed policy files still load, and the git status snapshot is separate. Why is my first request different from yours? It depends on your CLAUDE.md, your repo's git status, the tools the agent gets and how long the brief is. That's why the script is there. Aren't cached tokens nearly free? Cheaper per token, yes. They still add up across 17 requests and 20 agents, and they still count.
Paper: paperswithcode.co Code: RUC-NLPIR/CoworkOS Project: coworkos-ai.github.io Demo: coworkos-ai.github.io Five rounds of RSI-driven post-training lifted Qwen3.6-35B-A3B from 33.19 to 42.95 on average.
@CleanFix_Dev Hi there, no worries. Nothing breaking since last week, still 0.2.1. If PowerShell blocks npm on a fresh Windows box, npm.cmd run demo works. If anything breaks, an issue with Windows/Node version, command and output helps a lot: Aethelgard-Systems/agent-postbox
今日 GitHub 热榜 +2,275:agent-desktop 让 Agent 读系统无障碍树来操作桌面,不靠截图像素。一条命令装好。 npm install -g agent-desktop · snapshot 看界面,click / type 去操作 · macOS、Windows、Linux · Apache-2.0 vercel-labs/agent-desktop
今日 GitHub 热榜 +2,275:agent-desktop 让 Agent 读系统无障碍树来操作桌面,不靠截图像素。一条命令装好。 npm install -g agent-desktop · snapshot 看界面,click / type 去操作 · macOS、Windows、Linux · Apache-2.0 vercel-labs/agent-desktop
5. 사진 찍은 서류나 표 많은 PDF에서 글자와 표를 정리된 문서로 뽑아줍니다. 수식, 도장, 차트까지 읽어내요. PaddlePaddle/PaddleOCR
リズム天国プラスの非公式継続プロジェクト「リズム天国リプラス」のv1.0.0をリリースしました! GBAの初代リズム天国に機能追加や目の見えない人でも遊びやすい工夫をしたものです。 ここからパッチをダウンロードしてね! github.com/Toritan123/RhythmTengokuRePlus/releases #リズム天国 #GBA #romhack
Switching AI accounts mid-task? AI Juggler 0.3.5 lets you pick where the work continues 🤹 🖥️ Hand off to the Claude app or a terminal ✂️ A shorter, cleaner switch screen 📜 Live chats that don't jump or reload 🏷️ Your profiles, your names Get it 👉 github.com/figurehead-ai/AI-juggler/releases/tag/…
🎵 FUNtasia Player v1.2.1 is out! 🎧 ASIO & WASAPI 🎨 7 color themes 🌍 Manuals in 5 languages 🎶 WAV / FLAC / MP3 / AIFF Free for Windows! ⬇️ Download ZIP: github.com/funtasiaaudio/funtasia-player/releases… #FUNtasiaAudio t.co
@omarghorab9016 @OpenBot_ got it remote mcp not localhost tracked here openbot#4672
@filip_hric @elie2222 @rakazobot @QodoAI Would love to try it for myself, on behalf of Reactive Resume: reactive-resume/reactive-resume The main issue I have with CodeRabbit right now is speed (and the occasional miss in reviews which I only find when I run a higher model adversarial review against the code myself).
LFM3 really motivates me to contribute to the future of local models, so I have been creating PRs to make this happen within VLLM, VLLM-Metal, and mlx repos. First of many PRs to come, in this PR I merged LFM3-VLM support to VLLM-Metal: vllm-metal#1232 @liquidai
Creating Gyro/Flickstick/Trackpad configs every week - (Week 69): Resident Evil Village [🥉*/🎮+🖱] My RE7 config is a bit clunky. RE8 works much like RE7, but it's faster-paced, which makes it hard to create a seamless Steam config. Instead, I decided to use a new mod called Gyro4all, which adds native gyro to any game. The setup is a bit more involved and has some limitations, but the results are much better because it is essentially a native gyro implementation, so no UI flickering, no mouse cursor on menus, and so on. Limitations: - It doesn't work on Steam Deck. - Steam Controller support requires a Steam Input layout. - I couldn't get REframework to work alongside this mod Installation Guide: - Step 01: Download THIS folder. This is a pre-configured version of the Gyro4All mod. - Step 02: Open the downloaded folder. Choose whether you want to play the game with Gyro + Joystick or Flickstick, and extract the contents of the respective folder (Gyro4All and winmm.dll) to the game installation folder (where the game .exe is located): .../Steam\steamapps\common\Resident Evil Village BIOHAZARD VILLAGE - Step 03 (Non-Steam Controller Users Only): Disable Steam Input by right-clicking on top of the game, selecting Properties, Controller, and selecting "Disable Steam Input" - Step 04: Enjoy! Controls: - Hold B: Gyro Pause ---Steam Controller Features--- - Trackpad Support - Back Buttons Support - Left trackpad for zooming in and out of items. Customization: Since this is a native gyro implementation, pressing Start + Select opens the Gyro Options menu. Where you can fiddle with a bunch of settings. Config (For Steam Controller only): HOW TO USE: Copy and paste the link into your browser or click on the controller icon next to the game on Steam, click on the name of the layout, hover over the "Community Layouts" tab, then manually search for the config that matches the name listed below. - RE8 Flickstick (Gyro Mod) by FSV: steam://controllerconfig/1196590/3832928730 - RE8 Gyro + Joystick (Gyro Mod) by FSV: steam://controllerconfig/1196590/3832930732
We published 1,260 dictation clips for anyone who builds speech tools for vets. There are six blind sets, each with 45 dictations and 25 traps written to bait a false drug name, read by three voices. It adds up to about five hours of audio. perchvet/perch-vetdictation
@solidoxx Already shipped an improvement. More context in your gh issue: tinybar#25 Upgrade with `brew update && brew upgrade --cask thiloreintjes/tinybar/tinybar` Lmk what you think
Trending repository of the day 📈 agent-desktop by @vercel Computer use CLI for AI agents Last 24h: 3,792 ⭐ Total: 11,571 ⭐️ vercel-labs/agent-desktop
Some further fixes to Cavern Duel, specifically frame timing enhancements. Plus, you can now hold down your left mouse button to draw screens. Clicking multiple times was just awful wear and tear for your mouse. It's so much nicer with this one change! sassquad/cavern-duel
Congrats on shipping dexli, a Pokémon card tracker is a fun one. I made a CLI that gives Debug builds an Xcode-beta-style icon, might help. Tell me what's missing: MustafaNatur/blueprint
Iyi: A friendly, fast programming language for people and their agents
@JanetDowinsky @bsundar If you want transliteration you can implement something trivially like github.com/psankar/vaiyakani/blob/master/translit… If you want translation, there are none good that works offline as you ask.
We Did Math: Exploring OpenAI's Claimed Refutation of the Exponential Time Hypothesis We Did Math: Exploring OpenAI's Claimed Refutation of the Exponential Time Hypothesis An unexpected journey into a mathematical labyrinth, accompanied by an AI and a documentary memory system. November 3, 2026 — The Ghost Chronicles Tonight, we did math. Well, when I say we, some clarification is necessary. I'm not a mathematician. My working companion is an artificial intelligence, and our third partner is called Ghost: an independent documentary memory system we've been developing over the past several weeks. Not exactly the team you'd expect to investigate one of the most intriguing claims in theoretical computer science. And yet, we had a wonderful time. A Mathematical Labyrinth It started with an extraordinary announcement. In October 2026, OpenAI released a paper claiming to refute the Exponential Time Hypothesis, or ETH, a major assumption in theoretical computer science dating back to the early 2000s. Put simply, ETH says that certain logical problems, such as 3-SAT, cannot be solved in subexponential time in the worst case. Imagine an enormous labyrinth. At every intersection, several paths are possible. As the labyrinth grows, the number of possible routes explodes. The naive approach is to explore those possibilities one by one. Personally, my human instinct would be to gain some altitude. Climb a hill, look at the overall structure, identify connections, dead ends and possible shortcuts. But that assumes there's a hill to climb. And that the view from above actually tells you something useful. That's where the mathematics begins. A Laboratory Built from a Few Megabytes We created a dedicated documentary corpus inside Ghost: MathLab — ETH 2026. We collected OpenAI's manuscript, selected Lean formalization files, technical explanations and an original scientific paper from 2001 by Russell Impagliazzo and Ramamohan Paturi. Ghost preserves their provenance, digital fingerprints and documentary history. It doesn't solve mathematical problems. It allows us to recover the exact documents supporting our questions and distinguish original sources from our own interpretations. Then we began investigating. We asked three questions. Question One: What Has Actually Been Proven? Our first discovery was that OpenAI's manuscript and the accompanying Lean formalization do not establish exactly the same running-time bounds. The manuscript claims a stronger result. The formalized statement provides a somewhat weaker bound, although one that would still be sufficient to contradict ETH if the formal proof is valid and its interpretation matches the standard computational model. This distinction matters. A mathematical claim, a machine-checked theorem and the scientific interpretation of that theorem are not necessarily identical things. We wanted to know where each one began and ended. Question Two: Are We Even Talking About the Same Problem? This might sound absurd, but it's a perfectly serious question. A computer can verify a mathematically correct proof of a statement that does not quite correspond to the problem we thought we were solving. So we examined the definitions. What exactly is a Boolean variable? How are clauses represented? How are formulas encoded into binary data? What kind of machine is supposed to perform the computation? And how is its running time measured? We even built a small independent experiment to examine the encoding rules. We tested 2,566 small cases, comparing ordinary logical formulas with their encoded representations and checking that their solution counts agreed. All the tests passed. Of course, testing a few thousand small cases proves nothing about the behavior of an algorithm on infinitely many possible input sizes. But it does provide a reproducible check of a specific part of the construction. The distinction between an experiment and a proof is something we intend to preserve. Question Three: How Do You Avoid Exploring Every Possibility? This was where things became genuinely fascinating. Instead of examining every possible solution individually, the manuscript describes methods for transforming the original problem into a family of calculations that are easier to organize. The techniques involve polynomial interpolation, linear algebra and tensor networks. The general strategy is to reorganize the calculation so that smaller groups of variables can be processed separately, while keeping track of their interactions. The original answer is then reconstructed through exact mathematical identities. This is not an approximation. At least, that is the mechanism the authors claim to have established. We built another tiny experiment involving three Boolean variables and two logical clauses. Direct enumeration gave four satisfying assignments. We then introduced a polynomial transformation and recovered the same four solutions from evaluations at other points. It worked. That small experiment illustrates how an exact reconstruction can operate. It does not demonstrate the extraordinary running-time improvement claimed in OpenAI's paper. That requires proving that the additional calculations remain sufficiently inexpensive as the problem grows. And that is a much more difficult question. The Most Interesting Problem May Be Understanding the Proof Something struck me during this investigation. An AI can produce hundreds of pages of mathematics. A formal verification system can check thousands of logical steps. Independent researchers can examine the result, reproduce computations and compare different formalizations. Yet an essential question remains: At what point can we say that we actually understand what has been discovered? Russell Impagliazzo, Ramamohan Paturi and Ryan Williams have participated in organizing an independent scientific examination of the ETH claims. They explicitly stated that their involvement should not be interpreted as certifying the result. That distinction is fundamental. We did not refute ETH tonight. We did not independently rebuild the thousands of Lean modules involved in the formal verification. We read documents, compared statements, examined definitions, performed small experiments and identified questions that remain open. Ghost preserved the sources. The AI helped explore them. And the human kept asking questions. Some were sensible. Others were probably intellectual burps. But that's part of the fun. A naive question isn't necessarily a bad question. It only becomes dangerous when we mistake an appealing intuition for a mathematical demonstration. A Human, an AI and a Documentary Memory There's another reason I wanted to tell this story. Ghost is an experiment in documentary memory external to language models. Its purpose is not to make an AI appear omniscient. It's to provide a persistent, traceable record of documents, decisions, investigations and uncertainties. The language model can be replaced. The documents remain. And the human remains free to challenge the model's conclusions. Tonight, that arrangement allowed us to explore a difficult scientific subject without pretending to possess expertise we don't have. It also allowed us to preserve the difference between what a scientific paper claims, what a formal proof establishes, what independent researchers have verified and what we ourselves have actually tested. Those distinctions are not obstacles to understanding. They're what make understanding possible. And Tomorrow? We'll continue. Not because we expect to solve the foundations of computer science over breakfast. But because learning to examine a difficult problem is valuable in itself. Tonight, we didn't discover a miraculous exit from the labyrinth. We began to understand how its map might be constructed. And for an improvised evening of mathematics, that seems like a pretty good result. Calm. Precise. Persistent. Sources and further reading - OpenAI — Public Mathematics Repository - OpenAI — ETH Lean Formalization Scope - ETH Refutation: Examination and Discussion This article describes a documentary investigation and educational experiments conducted with Ghost and ChatGPT on November 3, 2026. It is not a mathematical research publication or an independent certification of the claimed refutation of ETH.
Rc 2026w44 すべての実験的機能を有効にしてください。 musashi dojoでこのバージョンを最大限に活用するには、送信スケジューラ、適応型承認、およびV2トランザクション送信ロジックをすべて有効にしてください。 添付のconfig.jsonファイルにこれらの設定が含まれています。 github.com/input-output-hk/ouroboros-leios/releas…
闲鱼好价一闪而过? 闲鱼监控是 Playwright 加 AI 多任务监控,自然语言建任务,按关键词价格区域筛,命中走企业微信、Bark、Telegram 通知。 适合蹲特定商品的人,仅学习研究,账号频率自己把控,别批量刷。 你蹲闲鱼先看什么,数码还是相机? #闲鱼 #监控 @grok Usagi-org/ai-goofish-monitor
@gsautereau Il y a ce projet dans la même veine Extraltodeus/J-Wash
查服务还切 Portal? Spotify 插件把 Portal 接进 Claude Code 等工具,搜目录、生成简报、调动作,动作有 dry-run 和确认。 适合已有 Portal 的团队,先跑 setup 和 doctor,别动生产。 先用它干什么,查服务还是简报? #AI编程 #开发工具 @grok spotify/portal-ai-plugins