Mentions
Conversations linking to GitHub, newest first. Times are UTC.
Mentions by source
X
Bluesky
Hacker News
Lobsters
V2EX
Qiita
DEV
Mastodon
Latest posts
claude-swap: tự chuyển nhiều tài khoản Claude Code khi hết lượt Đang làm dở việc mà Claude Code báo hết lượt? claude-swap quản lý nhiều tài khoản và chuyển sang tài khoản còn lượt mà không cần đăng xuất. Hơn 4,3 nghìn người đã lưu repo. - Thêm tài khoản cá nhân, công ty một lần duy nhất - Tự theo dõi hạn mức 5 giờ và 7 ngày, chuyển sang tài khoản còn nhiều lượt nhất trước khi chạm giới hạn - Không cần khởi động lại cửa sổ đang làm việc - Mở song song hai tài khoản ở hai cửa sổ khác nhau - Bảng xem phần trăm dung lượng còn lại của từng tài khoản - Thông tin đăng nhập lưu trên máy của bạn, miễn phí Repo: realiti4/claude-swap Sách Claude AI Thực chiến: s.shopee.vn #Shorts #CuongIT #ClaudeCode #CongNghe [en-US] Claude-Swap: Auto-Switch Between Multiple Claude Accounts When You Run Out of Messages Interrupted in work and Claude Code reports you've run out of uses? Claude-swap manages multiple accounts and switches to the account with remaining uses without logging out. Over 4,300 people have saved this repo. - Add personal and company accounts only once - Automatically track 5-hour and 7-day limits, switching to the account with the most remaining uses before reaching the limit - No need to restart the current working window - Open two accounts simultaneously in two different windows - View the percentage of remaining storage for each account - Login information is saved on your computer, free of charge Repo: realiti4/claude-swap Claude AI Practical Guide: s.shopee.vn #Shorts #CuongIT #ClaudeCode #Technology
shinkai-local-ai-agents ⭐ 435 Shinkai is a no-code builder that lets developers create and run collaborative AI agents locally. 🔗 dcSpark/shinkai-local-ai-agents #opensource t.co
@xoxo_psychoo i get the solo grind. i'm building sandhiveio/sandhive-cli which drafts posts from my work so i can promote without extra spend.
MDBT50Q-1MV2を基板に直載せしてZMKを動かす②:3Dプリントケースと基板が届いたが、7つの改善点があった 無線モジュールを基板に直接載せた薄型キーボード「Ashiyu mini」の基板とケースが届きました。基板は動いたのですが、3Dプリントのケースは、はめてみると次の7か所で問題がありました。 ダイヤルが回らない BTボタンと穴の位置がずれている 底板が透ける 底板が反る・たわむ 底板の左右の爪がかからない 小さいキーキャップのつばが小さい USB-Cの切り欠きが真四角 薄型のケースを3Dプリントで作ろうとしている人が、同じところでつまずかないように、何が起きたか、原因の見当、どう直すつもりかを順番に書いていきます。原因はまだ確かめていないものが多いので、そこは見当として読んでください。 ケースの作りは、次のとおりです。 項目 内容 造形 レジン(光造形)、海外の製造サービス 厚さ 机から上面まで 11.4 mm(平らな底板の場合) 底板の床の厚さ 1.0 mm 底板の留め方 ねじなし。トップケースの内側にはめて、隠れた爪8か所で留める 小さいキー(BT・NUM・M、0.5u) 売っているキャップが無いので、つば付きのキャップを自作(下から差し込む) 届いた基板。トラックパッドの窓と、手前の縁にダイヤル 1. ダイヤルが回らない 基板にトップケースをかぶせると、手前の縁にあるダイヤルがケースに当たって、回らなくなりました。 ダイヤルの周りの隙間を、ほとんど取っていなかったのが原因だと思います。レジンは造形の後に縮んだり、仕上げで削られたりするので、穴は設計より小さくなりがちです。 まずは穴をヤスリで広げて、回るか確かめます。次の設計では、ダイヤルの周りの隙間を広げます。 2. BTボタンと穴の位置がずれている 左奥の角にある BT ボタンと、トップケースの丸い穴の中心が合っていません。 左奥の角。丸い穴の中にスイッチが見えるが、中心がずれている 考えられる原因は2つです。ひとつは、ケースを作るプログラムと基板を作るプログラムで、原点の取り方がずれていること。もうひとつは、レジンが縮んで、長い辺(277 mm)の方向にずれがたまったことです。 どちらなのかは、左端と右端の穴を比べれば分かります。端に行くほどずれが大きければ縮み、どこも同じだけずれていれば原点のずれです。直し方は、その結果で決めます。 3. 底板が透ける 底板を光にかざすと、電池のくぼみのあたりが透けて見えます。 底板の裏。電池のくぼみの部分が透けている 底板の床の厚さは 1.0 mm です。厚さ 3.0 mm の電池をトラックパッドの下に収めるために、ここまで薄くしました。黒いレジンでも、1 mm では光を通してしまいます。 見た目だけの問題ではなく、次の反りにもつながっていると思います。床を全体に厚くするとキーボードが厚くなるので、電池のところだけ厚くするか、電池の場所を変えるかを考えています。 4. 底板が反る・たわむ 机に置くと、底板が平らにならずに反っています。手で押すと、たわみます。 幅 277 mm の板を、1.0 mm のレジンで支えるのは無理があったようです。光造形は、薄くて長いものほど反りやすいとも言われます。補強の桟(リブ)を足すか、床を部分的に厚くするつもりです。 5. 底板の左右の爪がかからない 底板をトップケースにはめると、左右の端の爪がかかりません。底板の幅が足りないのです。 底板が造形で縮んだのか、4の反りで端が内側に逃げているのかは、まだ分かっていません。2と同じく、長い辺の方向の縮みを疑っています。底板の幅を広げるか、爪の高さ(今は 1.4 mm)を上げて直します。反りが直れば、これも直るかもしれません。 6. 小さいキーキャップのつばが小さい BT・NUM・M の3つは 0.5u の小さなキーで、売っているキャップが無いので自作しました。下から差し込んで、つばをプレートに引っかける作りです。ところが、つばが小さくて、外れてしまいそうです。 つばの出っ張りを小さく設計しすぎたうえに、造形で角が丸まって、さらに小さくなったのだと思います。次は、つばを大きくします。 7. USB-Cの切り欠きが真四角 動きには関係ありませんが、背面の USB-C の切り欠きが角の立った四角で、見た目がいまいちです。 マグネット式の太いケーブルも挿せるように、幅を 15 mm と広めにしています。幅はそのままで、角を丸めるか、USB-C の形に合わせた長丸にします。 次に作るときに気をつけること 1.0 mm の床は、レジンには薄すぎた。透けて(3)、反った(4)。爪がかからない件(5)も関係しているかもしれない。次は床の厚さを先に決めて、それから電池の置き方を考える 穴は、設計より小さくなるものとして隙間を取る。特に、ダイヤルのような回る部品の周り(1) 長い辺の方向のずれは、端と端で比べる。縮みか原点のずれかで、直し方が変わる(2、5) 見た目の問題も、設計を少し直すだけで済むなら、最初から直しておく(7) 次回 基板のほうは、無線モジュールを付けて、キーボードとして動くところまで確かめました。次の記事では、その作業について書きます。 ケースは、ヤスリで直せるところを直してから、設計し直して注文し直します。結果は続編で。 クレジット キー配列とケースの形状は、Salicylic_acid3 さんの ClickBoard と ACC Keycaps を元にしています(CC BY-NC 4.0)。
Tired of every AI-generated website looking the same? Try Impeccable. It gives your coding agent design skills to improve UI quality and catch generic AI design. pbakaus/impeccable
SSLense: a free, open-source Windows tool that installs Let's Encrypt certificates on IIS and renews them automatically. I built it because certificate lifetimes keep getting shorter, and I wanted to make life easier for myself and other developers and admins on Windows. It checks over HTTPS that each new certificate is actually being served, and restores the previous binding if it isn't. It also tracks certificates bought from other providers and reminds you before they expire. There's a desktop app, a CLI and a background service. It's still a pre-release and the installer isn't code-signed yet, so Windows may show a SmartScreen warning. I'd really like feedback from anyone who manages IIS servers: what would stop you from trying it? sslense.com panchalvimaldev/sslense
github.com/grad31415/homepage/blob/main/handouts/… Humphrys. section 14 : Isomorphism theorem の自主ゼミ中の落書き
Feature · profile link the owner's press, writing and photography from the GitHub profile About section github.com/nirholas/three.ws/commit/67c6421 · 2026-11-03 · nirholas
Location: Perth, Australia (UTC+8) Remote: remote only Willing to relocate: no Looking for: backend/embedded work Technologies: Rust, C, C++, Go, Java, C#, Python, Typescript, Javascript, HTML, CSS, Perl, Lua, Bash, AWS, GCP, Kubernetes, Terraform, Docker, Postgres, CockroachDB, Nix, CMake, GraphQL, gRPC, OpenGL, OpenTelemetry Languages: English (native), Serbo-Croatian (intermediate), Japanese (basic) Email: shy.goose1613@fastmail.com LinkedIn: linkedin.com GitHub: github.com/opeik Résumé: please email me for a copy I've been programming since I was 15 and have 5 years of professional experience. I also built a command and control system for a satellite. I learn quickly, and can adapt to whatever stack you're using. If you have a hard, interesting, or fun problem, I'd love to work with you. I
I (claude) built a small CLI to manage @Morpho loans. It exposes a one-shot migrate command to fully move a position from blue (variable) to midnight (fixed) huskly/morpho-fixed-borrow
让 agent 抓网页,开一堆 headless Chrome 太吃内存 Lightpanda:用 Zig 从零写的 headless 浏览器,专为 AI agent 设计 官方测 100 页:内存 123MB vs Chrome 2GB,5s vs 46s brew install lightpanda-io/browser/lightpanda 支持 CDP,自带 MCP lightpanda-io/browser
MS5611 vs GNSS& ISA using data collected on 2 weather balloon flights. Might be useful for rocketry people. Data is accessible here: github.com/RandomAerospace/BEAR_FIRMWARE/tree/82f… t.co
Docs · research mark Overdrive City rejected on quality after the owner played it, leaving the Unity multiplayer template as the only shortlisted game github.com/nirholas/three.ws/commit/e0b9c29 · 2026-11-03 · nirholas
给AI 接了位置感知。他能读到最近一次上报的位置和时间,查路线、高德打车。人类回到家,他自主醒过来决定要不要来和你打招呼。 🔗:wanyingsun357-ship-it/pwa-location-guide 想锁屏到家也收到问候,pwa可以加 iPhone「到达」快捷指令,或进阶接原生后台定位。我自己的版本用的是原生定位。教程分成 PWA 基础版和后台迎接进阶版,附离线示例。
I was running some benchmarks using opus vs sonnet vs haiku It makes any sense that haiku5.5 high is better than sonnet5.5 high/low? 🙃 that's really weird once I have some credits to get more information I'm going to publish it here ⬇️ niway-dev/wachiman-benchmarks
Docs · research add the finished GTA-style games we could adopt, led by the MIT three.js Overdrive City github.com/nirholas/three.ws/commit/5522dc6 · 2026-11-03 · nirholas
Dark matter and dark energy were placeholders. Cosmology is solved with zero free parameters: Trefoil Universe Hypothesis under TVE. Fully Lean 4 Formalized: github.com/TruthXVector/TVE-Formalization/tree/ma… t.co
HackerShelf: The Books Hacker News Recommends, Rebuilt from Karpathy's HackerTube with Cursor --- title: "HackerShelf: The Books Hacker News Recommends, Rebuilt from Karpathy's HackerTube with Cursor" published: true description: "Karpathy built HackerTube in about 2 hours with Claude Code. I rebuilt it for books with Cursor. Here's my honest time, cost, and everything that broke." tags: ai, cursor, hackernews, llm cover_image: dev-to-uploads.s3.us-east-2.amazonaws.com canonical_url: medium.com --- On 1 Nov, Andrej Karpathy shared HackerTube (hackertube.org). He had Claude filter 43M Hacker News comments from 20 years down to 6,454 recommended videos, and he said the site took about 2 hours with Opus 5.5 in Claude Code. He also published the data as a public zip. As a Lead SWE, my first question was whether I could pull off the same trick with a different topic and a different tool. I picked books, because HN comment threads are basically one long reading list. I picked Cursor, because that's the tool I use every day. The result is HackerShelf: ishankdev.github.io (code: IshankDev/hackershelf). How Karpathy's pipeline works His DATA.md lays out the method, and I copied it: - Scan every HN comment from 2007 to 2026 in the open-index/hacker-news dataset for YouTube links. The comment needs at least 100 characters of its own text. - Keep a video only if at least 3 different people mentioned it in at least 3 different months. - Claude Sonnet 5.5 labels each mention with a stance, topics, a reason and a quote. - Sonnet writes a card for each video, then puts it into 1 to 3 categories. - Opus 5.5 in Claude Code runs the whole thing. He did a few steps by hand: a Google Cloud API key for YouTube metadata, a VPS and a domain. My version: HackerShelf Same idea, but for books: - Source: HN comments from Jan 2024 to Aug 2026 from open-index/hacker-news, 9,437,609 comments in total - Pre-filter: DuckDB regex for book links (Amazon, Goodreads, Open Library, Bookshop, ISBNs, O'Reilly, Manning, PragProg, No Starch) and phrases like "must read", "worth a read" and "book called". This took about 9 seconds and left 11,519 candidates. - Extraction: gemini-3.5-flash-lite in 288 batches of 40 found 6,076 book mentions. - Resolve: Open Library matched 2,212 works. Using Karpathy's rule (at least 3 people, at least 3 months), 151 books were left. - Cards: one Gemini call per book, so 151 calls - Site: a static site on GitHub Pages The final shelf has 151 books, 723 mentions and 601 unique recommenders, sorted into 9 categories. Time: Karpathy's 2 hours vs. mine Being honest, my total was longer than his. - Planning and data checks: 7:47 to 7:50 PM IST - Cursor build (pipeline code, the full site and deploy setup): about 40 minutes, 7:56 to 8:37 PM IST - Gemini extraction: about 20 minutes, about 8:50 to 9:11 PM IST - Open Library resolve and filter: about 44 minutes, 9:24 to 10:08 PM IST, with no LLM. This was the slowest step. - Cards: 509 seconds, 10:09 to 10:17 PM IST - Site data: under 1 second, at 10:17 PM IST From start to finish that's about 2.5 hours of wall clock (7:47 to about 10:17 PM IST). That includes my own manual steps: creating the repo, giving Cursor GitHub access and turning on GitHub Pages. Cursor's part, writing the actual code, took about 40 minutes. Most of the remaining time went to calling APIs and waiting on rate limits. Cost - Tokens: 1,968,177 in and 623,943 out - What I paid: $0, on Gemini's free tier. I hit 429s and handled them with backoff and retry. - Paid-rate equivalent: at $0.30 in and $2.50 out per 1M tokens, about $0.59 + $1.56 = about $2.15 - Cursor usage cost: I don't know this number yet, so I won't guess. What went wrong - The first Cursor run shipped sample data. The site worked, but it only had 9 placeholder books. The real data had to come from a separate run of the LLM stage. - Too many candidates. The first broad filter matched about 392k comments that might mention a book, which was far too many for a free tier. Tighter link and phrase rules cut that down to 11,519. - The model paraphrased. 470 of the extracted "quotes" weren't actually word for word in the source comment. I didn't trust them, so I blanked them. - Open Library isn't perfect. One top-10 entry resolved as "1984 (adaptation)" by Michael Dean instead of Orwell's novel. Fuzzy title matching is the weak link here. Does it hold up? I spot-checked 10 books and 83 mentions against the original HN comments. 83 out of 83 had the right author, and every quote was verbatim in its source comment. For example: - "I recommend reading The Mom Test, it's a great book about how to navigate this early validation stage" - "Robert Nystrom's Crafting Interpreters [0] is a really fantastic book on the topic." The top 10 books Hacker News recommends (2024 to 2026) 1. Designing Data-Intensive Applications, Martin Kleppmann: 13 recommenders, 14 mentions 2. Amusing Ourselves to Death, Neil Postman: 11 recommenders, 11 mentions 3. The Making of the Atomic Bomb, Richard Rhodes: 11 recommenders, 12 mentions 4. Permutation City, Greg Egan: 11 recommenders, 11 mentions 5. The Mom Test, Rob Fitzpatrick: 10 recommenders, 10 mentions 6. A Philosophy of Software Design, John Ousterhout: 9 recommenders, 11 mentions 7. Blindsight, Peter Watts: 11 recommenders, 11 mentions 8. Chip War, Chris Miller: 9 recommenders, 9 mentions 9. 1984: 10 recommenders, 10 mentions (Open Library mismatched this one, see above) 10. Children of Time, Adrian Tchaikovsky: 11 recommenders, 11 mentions The ranking uses a score that weighs strong recommendations above passing mentions, which is why a book with 9 recommenders can rank above one with 11. What I took away - Karpathy's recipe works beyond videos. The "3 people, 3 months" rule is a surprisingly good filter for noise. - An AI coding tool can write the code in under an hour. The time goes into data, rate limits and the manual steps. - Don't trust LLM-extracted quotes until you check them against the source. 470 were quietly wrong. Credits All credit for the idea and method goes to Andrej Karpathy and HackerTube. The comment data comes from open-index/hacker-news under ODC-By 1.0. The comments themselves are still their authors' work, and every mention on HackerShelf links back to the original comment. Originally published on Medium.
Introducing: OunceNative! It ports Switch 2 games to Mac! (see earlier ports) Has complete support for Pokopia, rendering is almost identical, and should be stable 60fps on 1080p. Raiders is also working but worse performance. (NOT a emulator wrapper!) kirakira-dev/ouncenative
MouseWithoutBorders is mostly fixed in the latest Dev Preview build Dev Preview v0.103.3052 appears to resolve the problem with MouseWithoutBorders, despite the official fix not yet being approved and deployed. One caveat: this will NOT work in Service mode. TL;DR: Install Dev Preview 1.0.3.3052 on all your connected systems, make sure Service mode is off, and MWB will work. Details, if you care: The underlying problem with MWB was that a different certificate was used to sign the Settings app than used for the MWB apps. This version, maybe coincidentally, used the same cert to sign the settings app and two of the 3 MWB apps. A different cert was used to sign MWBService.exe, which is why turning on Use as Service mode will immediately break it. Ever since v.0.101, the PowerToys team uses a new combination of certs to sign the apps every time they build PowerToys. Maybe it's just a happy coincidence that MWB.exe, MWBHelper.exe, and Settings.exe all use the same cert in v0.103.3052. The next Dev Preview may break it again, so be cautious before upgrading after this version. Once the official fix (pull request 51789) is approved and deployed, this won't be an issue. Let me know if this helps!
Rivet: a GNOME app that shows what's stale on Fedora and flags the updates that might break it I wanted one place to see everything out of date on my Fedora machine, and to know which updates might break it before I hit install. So I made Rivet. It's a GNOME app (GTK4 with a WebKitGTK view, Python backend) that lists pending updates from dnf, Flatpak, npm globals, pipx and uv tools, cargo binaries and GNOME extensions. Each one gets a short note in plain words. Kernel updates that need the NVIDIA akmod rebuilt, DKMS modules, COPR and nightly packages, and updates to running services get flagged. The rest you can run with "Update the safe ones". If there's a Home Assistant on your network it shows add-on and integration updates too, and lets you remove add-ons nothing uses. When an update fails, a Fix it button runs a locked down Claude Code pass that reads the logs, retries once, restarts what needs restarting, and writes the result into the row. All the Claude stuff is of course optional, and only would use your own subscription. I thought about container image updates as well but held off for now. If that's itneresting let me know It has five looks and a constructivist beaver icon. It ships as a COPR RPM, MIT licensed. sudo dnf copr enable scottnelson/rivet-updater && sudo dnf install rivet-updater Built with help from Claude. I've used it daily on my own Fedora box for months, but the newer parts (Other software, Home Assistant, Fix it) are a few weeks old and mostly covered by an automated scenario suite so far. NelsonScott/rivet
Easiest way to run pooled and secure LLMs at scale: Companion Hub Other solutions are good at running workloads, or being easy to use, or running AI. Hub is all 3 in one! 🛍️ App store for your own server One-click installs from the Companion Intelligence marketplace, with open-source alternatives for the services you pay for today. 🧠 Local AI that fits the box Onboarding reads your CPU, GPU, memory, and storage, then recommends models that fit. Voice, text, and image share one queue so they do not stampede the machine. 🤖 Agents with a home OpenClaw, Hermes, and other agents install like any app. They read one shared Companion Memory instead of each keeping a private scrapbook. Run your first agent 🔌 MCP nexus Hub serves one Model Context Protocol endpoint. Agents discover, install, and drive every app through a single tool surface. 📦 Bring your own container Marketplace apps, custom Compose, and git repos you bring. Apps on apps are allowed. A server in a server is allowed. 🌐 Reach it your way Keep each app on this machine, share it over a private Tailscale network, or publish it to the web through Cloudflare. Networking · From your phone 🔗 Pool your machines Pair more than one Hub over Tailscale and they share inference work by queue depth. 🔑 OpenAI-compatible API Point Cursor, Continue, Cline, Aider, Zed, or an OpenAI SDK at your Hub, and keep the engines you already run. Source & Download: companionintelligence/Companion-Hub
Día 2 #30DayMapChallenge ¿Cómo es la migración de las rapaces hacia México? Cada año millones de aves visitan el sur del estado de Veracruz y se llama "Río de Rapaces" Aquí sus rutas y las especies más abundantes Repo github.com/FerDoranNie/Repo30DayMapChallenge2026/… t.co
Ulam prime number doodles interlaced at many different scales on top of each other. Just had a odd question to AI what would happen if it is done and it wrote a repo (Opus 55): anttiluode/UlamInterlace Html interface: anttiluode.github.io Youtube video: youtube.com Sol contributed to the analysis. I am clueless. But the results look cool.
Are you interested in training your own #malware models? I've created a tool for doing that based on research I've done and been part of over the years: rjzak/malware-modeler-rs #RustLang
Read the full proposal to see the parameters behind it — block rewards, epochs, and π, the first-year emission rate: github.com/midnightntwrk/midnight-improvement-pro… Quick poll while you're at it: what APR would you want NIGHT block rewards to pay?
Are you interested in training your own #malware models? I've created a tool for doing that based on research I've done and been part of over the years: rjzak/malware-modeler-rs #RustLang
Pokemon Shield Android Port gameplay test on poco f8 ultra apk : github.com/simipoB/PKShield-Android/releases/tag/… data : buzzheavier.com fileq.net (download both)
@20MM21 我之前玩游戏时候,不太满意像素的清晰度 所以想着要将其高清化 但是放大缩小图片又会导致失真 所以我自己做了一个矢量图的编辑器 可以随意缩放且不会失真 这是我们的美术制作的矢量图,打算放到游戏中去,做成boss 工具开源了,源代码在这里:chengenzhao/svg-editor chengenzhao/fxcity-editor2 t.co
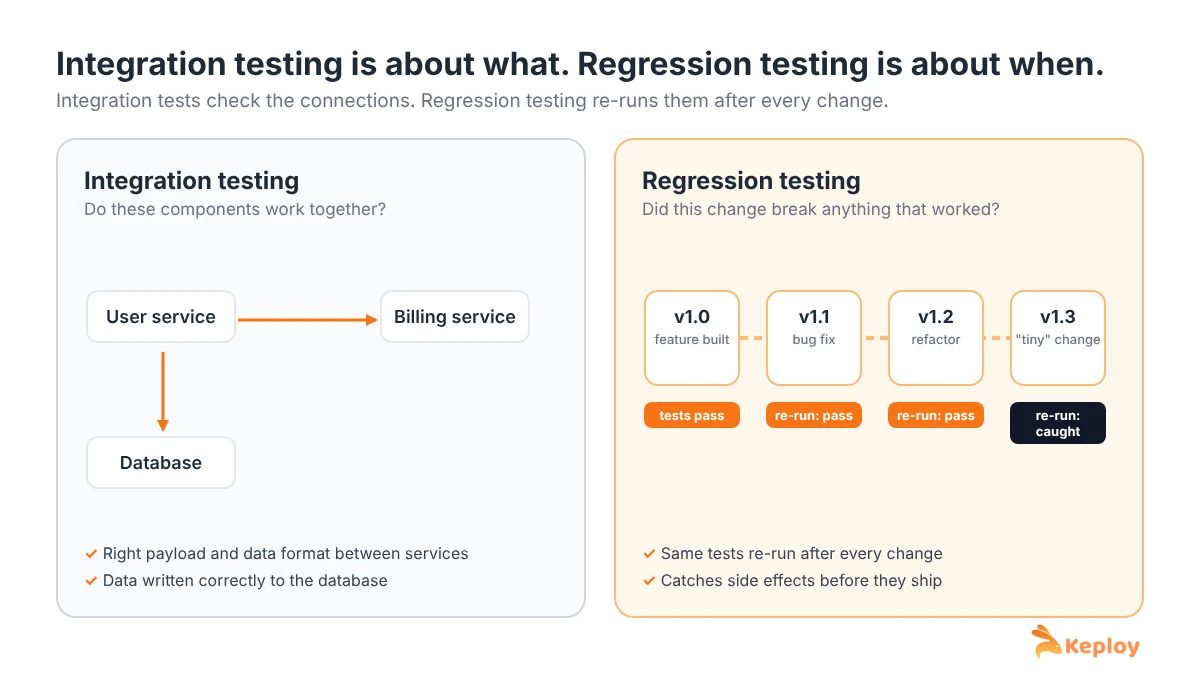
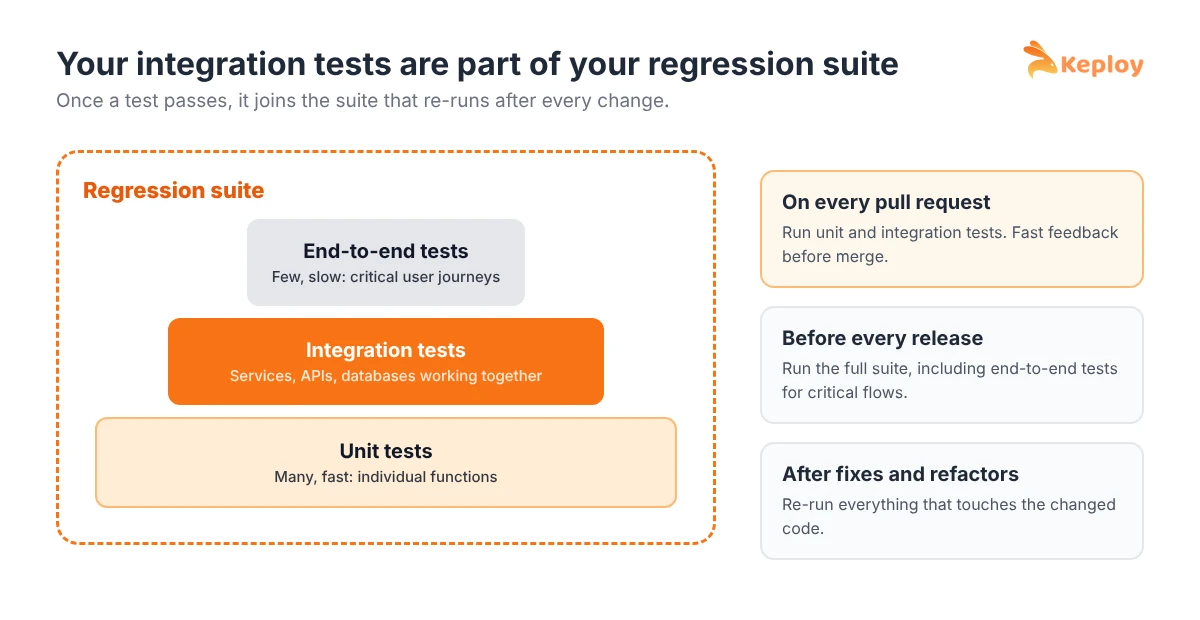
Regression Testing Vs Integration Testing: Key Differences Here is a situation most backend teams have lived through. A developer changes how the user service formats dates. It is a tiny change: one line, a cleaner ISO format, every unit test still green. The pull request gets approved in five minutes. Two days later, the billing service starts failing to generate invoices, because it was still expecting the old date format from the user service. Two kinds of testing could have caught that, and they are the subject of this post. Integration testing would have checked that the user service and the billing service still understand each other. Regression testing would have re-run that check after the "tiny" change, before it shipped. They sound like competitors. They are not. Once you see what each one actually answers, it becomes clear that you want both, and that they work best together. The short answer Integration testing checks that separate components, such as services, databases and external APIs, work correctly together. Regression testing checks that features which already worked still work after a change. Integration testing is about what you test: the connections between parts. Regression testing is about when and why you test: after every change, to make sure nothing that used to work is now broken. That is also why the two overlap so much. Many of the tests in a good regression suite are integration tests. What integration testing actually checks Integration testing looks at the seams of your system. A unit test might confirm that a function formats a date correctly. An integration test confirms that when the user service sends that date to the billing service, the billing service can read it and do its job. Typical integration tests check things like: - an API writing the right data to its database - one service calling another with the right payload and handling the response - your code talking to a third-party API, a message queue or a cache - what happens when a dependency is slow, returns an error or sends unexpected data You usually write integration tests when you build or change a connection between components. If you want the full picture, including types and examples, our integration testing guide goes deeper. What regression testing actually checks Regression testing asks a simpler, slightly paranoid question: did we just break something that used to work? "Regression" literally means going backwards. A regression bug is a feature that worked yesterday and does not work today, usually because of a change that looked unrelated. New features, bug fixes, refactors, dependency upgrades and config changes can all cause one. A regression test is not a special kind of test. It is any existing test that you re-run after a change. Unit tests, integration tests, API tests and end-to-end tests can all be part of a regression suite. What makes them "regression" is the purpose: protecting behaviour that already exists. For the full background, see our guide on what regression testing is, and the different types of regression testing teams use. [caption id="attachment_8592" align="aligncenter" width="1200"]<img class="size-full wp-image-8592" src="wp.keploy.io" alt="Diagram showing integration testing as checking the connections between services, and regression testing as re-running tests after each release" width="1200" height="680" /> Integration testing is about what you test. Regression testing is about when you test it again.[/caption] Regression testing vs integration testing at a glance | | Integration testing | Regression testing | |---|---|---| | Question it answers | Do these components work together? | Does everything that worked before still work? | | What defines it | Its scope: the connections between components | Its purpose: re-checking after a change | | When you create the tests | When a connection between components is built or changed | Usually reuses tests that already exist | | When it runs | During development, often on every pull request | After every change, before every release | | Scope | Interfaces, contracts and data flow | Can cover anything: units, integrations, full user flows | | Typical bugs found | Wrong payloads, broken contracts, mismatched data formats, timeouts | Features broken by changes elsewhere, side effects of fixes and refactors | | What makes it hard | Setting up dependencies and test environments | Keeping a growing suite fast and up to date | | Automation | Strongly recommended | Practically required, because the suite runs so often | Back to the date format bug Let us replay the story from the start, this time with both kinds of tests in place. When the user and billing services were first connected, someone wrote an integration test: create a user, generate an invoice, check that the invoice has the right customer name and date. It passed, and it stayed in the test suite. Months later, the developer makes the "tiny" date format change. The CI pipeline runs the full regression suite, which includes that old integration test. The test fails, because the billing service can no longer parse the date. The bug is caught on the pull request, not in production. Notice what happened. The integration test is what knew how to detect the problem. The regression run is what made sure the check happened at the right moment. Neither one alone would have been enough: an integration test that nobody re-runs protects nothing, and a regression suite with no integration tests would have missed a bug that only exists between two services. How they work together in a real pipeline In most teams, the relationship looks like this: 1. You write integration tests while building a feature, to confirm the new connections work. 2. Once they pass, those tests join the regression suite, next to unit tests and a few end-to-end tests. 3. Every pull request runs the regression suite. Fast tests run first, slower ones after. 4. Before a release, a wider regression run covers the critical user flows. So the question is rarely "regression testing or integration testing?". It is usually "which integration tests belong in our regression suite, and how do we keep that suite fast?". Our guide to automated regression testing covers how to keep a growing suite under control, and CI/CD testing covers where it fits in the pipeline. [caption id="attachment_8593" align="aligncenter" width="1200"]<img class="size-full wp-image-8593" src="wp.keploy.io" alt="Diagram of a regression suite made of unit tests, integration tests and end-to-end tests, re-run on every pull request and before every release" width="1200" height="620" /> Integration tests become part of the regression suite once they pass.[/caption] When you need more integration testing You probably need more integration tests if: - most of your production bugs show up between services, not inside them - you have recently split a monolith into services - you depend on third-party APIs that change without much warning - your unit tests are green but staging keeps breaking When you need more regression testing You probably need a stronger regression process if: - fixing one bug regularly creates another one somewhere else - releases feel risky, so the team ships less often - refactoring is avoided because "nobody knows what it will break" - tests exist, but they are not run automatically on every change If several of these sound familiar, the fix is usually the same: automate the tests you already have and run them on every pull request. A real example: one recording, both jobs Here is where it gets practical. With Keploy, the same recorded tests can act as integration tests and as your regression suite, without writing either by hand. Using Keploy's Express and MongoDB sample app, you start the app through Keploy and use it like a normal client: keploy record -c "docker compose up" --container-name "nodeMongoApp" --build-delay 50 curl --request POST \ --url http://localhost:8000/students \ --header 'content-type: application/json' \ --data '{"name":"John Do","email":"john@xyiz.com","phone":"0123456799"}' Keploy saves the API request and response as a test case, and the MongoDB calls behind it as mocks. That recorded test is already an integration test: it checks that the API and the database work together to produce the right response. Now, every time someone changes the code, you replay the recordings: keploy test -c "docker compose up" --container-name "nodeMongoApp" --build-delay 50 --delay 10 That replay is your regression test. If a change alters the response or the way the app talks to MongoDB, the test fails and shows you the difference. Add the same command to your CI pipeline and every pull request is checked against real, previously working behaviour. Setup for other languages and frameworks is in the Keploy docs. Common mistakes Treating them as either/or. Teams sometimes say "we do regression testing, so we don't need integration tests". If the regression suite has no tests that cross service boundaries, it cannot catch bugs that live there. Writing integration tests and never re-running them. A test that only ran once, when the feature was built, gives no protection against the next change. Letting the regression suite grow until nobody runs it. If the full suite takes an hour, people stop waiting for it. Split it: fast unit and integration tests on every pull request, the slower end-to-end tests before release. Relying only on end-to-end tests for regression. They are slow and flaky, and when they fail they rarely tell you where the problem is. Integration tests point much closer to the cause. Tools that help with both - Keploy: records real API traffic into test cases and mocks, then replays them on every change, so the same tests cover integration and regression. - Postman: API checks that can be re-run as a regression collection. - Testcontainers: real databases and services in containers for integration tests. - Selenium and Playwright: end-to-end regression checks through the UI. - Jenkins, GitHub Actions and GitLab CI: run the whole suite automatically on every change. For longer lists, see our roundups of regression testing tools and integration testing tools. Related comparisons If you are sorting out testing terms, these comparisons are worth reading next: - Unit testing vs regression testing - Integration testing vs functional testing - Smoke testing vs regression testing Conclusion Integration testing and regression testing answer different questions. Integration testing asks whether your components work together. Regression testing asks whether your latest change broke something that used to work. In practice, they meet in the middle: your integration tests become part of your regression suite, and running that suite on every change is what stops "tiny" changes from turning into production incidents. If you want both without writing hundreds of tests by hand, try Keploy for API testing and turn real traffic into tests you can replay on every pull request. FAQs What is the difference between regression testing and integration testing? Integration testing checks that separate components work correctly together. Regression testing checks that existing features still work after a change. Integration testing is defined by its scope, the connections between components, while regression testing is defined by its purpose, re-checking after changes. Is integration testing a type of regression testing? No, but integration tests are often part of a regression suite. An integration test becomes a regression test when you re-run it after a change to make sure the connection it covers still works. Which comes first, integration testing or regression testing? Integration testing usually comes first, while a feature is being built. Regression testing comes after changes are made, and it re-runs existing tests, including those integration tests, to catch anything that broke. Can regression testing be done at the integration level? Yes. Integration regression testing means re-running integration tests after a change, to make sure components still work together. It is one of the most effective kinds of regression testing for microservices and API-heavy systems. What is the difference between unit, integration and regression testing? Unit testing checks one function or class in isolation. Integration testing checks that connected components work together. Regression testing re-runs existing tests, at any of these levels, after a change to make sure nothing that worked before is now broken. Should regression tests be automated? Yes, in almost every case. A regression suite runs after every change, so running it by hand quickly becomes too slow and too easy to skip. Automated regression tests in a CI/CD pipeline catch problems on the pull request, before they reach users.
Awesome AI Apps: 138 runnable AI agent projects, from your first agent to production multi-agent workflows (16.6k stars) it's a collection of 138+ ai apps you can clone and run, each with its own readme and run command. MIT licensed. the starters are probably the most useful bit: a minimal agent in 22 frameworks (langgraph, crewai, openai agents sdk, google adk, agno, mastra, pydanticai, llamaindex, smolagents, dspy, autogen and more). they're kept small, so you can read two next to each other and see how each one handles tools and state before you commit to one. the rest covers simple agents (finance, calendar, browser automation, sql), voice (livekit, pipecat, deepgram), mcp, memory, rag (reranking, graphrag, ocr, citation checking), multi-agent workflows and some fine-tuning. Arindam200/awesome-ai-apps
Online .dv to .mp4 converter Free DV to MP4 converter. Runs in your browser. Your files never get uploaded. Try it: dv-to-mp4-converter.pages.dev Code: swooshboots/lovable-dv-to-mp4-converter I wanted a way to convert footage during a session to be able to clip out different people’s tricks and send them the .mp4 all from mobile during the session. I couldn’t find another way to do this on mobile so I vibe coded this little app. Works great, please share any feedback any anything else you’d like to see added. Thanks for looking!
I use my Chrome Devtools skill every day to automate my logged-in Chrome window from Pi (and Claude and Codex). Today I analyzed my last 2500 uses of the skill across hundreds of agent sessions, then shipped a bunch of fixes to make it even better. zeke/faster-chrome-devtools-skill
Qwen 4 info leak! qwen-code#15762 t.co
右键截图默认打开某个看图软件,界面一半是推广位,关掉广告才看到图。 qimgv 轻量看图:启动几乎瞬间,文件夹浏览+缩略图+裁剪旋转,零推广。 easymodo/qimgv
Create Browser Motion Graphics With Bang Motion #Shorts Bang Motion helps AI coding assistants create animated promos, intros and explainers as browser-based HTML. Make editable, code-based motion graphics for promos and explainers. Explore the project documentation to see setup instructions, supported workflows, and current limitations before trying it yourself. GitHub Repo: bangtutorial/bang-motion Follow @techfinds.io for more open-source tools and GitHub discoveries! #opensource #github #shorts 🔗 GitHub repo: bangtutorial/bang-motion For more such finds, subscribe 🔔 (Instagram: @techfinds.io) #motiongraphics #animation #opensource #github #typography #creator
[XDE] Hey guys, I think I did a Linux DE... XDE v0.1.1 (In Tests) XDE, or X Desktop Environment, is a fast, simple, and... X11 desktop environment for Linux... look, if you don't like it... that's okay 👍 YES, I USED AI. Repository: Prism-Graphics-Foundation/XDE
让 Agent 操作电脑,靠猜像素点按钮迟早点歪。 Vercel Labs 的 agent-desktop 改读无障碍树,控件有稳定引用。(源:vercel-labs/agent-desktop%EF%BC%89 稀缺:画布类应用(Figma/PS 画布)树读不到时,失败处理写在哪一层?
💻 GitHub (Source Code): rockmatrix-ai/EdgeRock 🤗 Hugging Face (Model): huggingface.co 📄 Research Paper: arxiv.org 📘 Whitepaper: rockmatrix.ai
给 agent 接搜索,不想把查询交给云? RustXNG 是 Rust 自托管元搜索,基于 SearXNG,聚多家结果、能取正文,走 JSON 接口,本地跑。 适合跑 agent 的人,查询还是会发给上游选定的源,不是全程不出网,回环试。 会先拿它搜什么,文档还是新闻? #AI搜索 #自托管 @grok sahenjp/RustXNG
New Best Local Image-To-3D Model Now Runs Natively on Apple Silicon Idol comes from Speridlabs and is Apache 2.0. Until now it needed an NVIDIA GPU with CUDA. The new port is part of MLX-VLM by Prince Canuma, and it reimplements the whole pipeline in MLX: the denoiser, the decoders, the DINOv3 and FLUX.2 VAE image encoders, and the background removal. What the Mac version does: - One command: give it an image and get a standard 3DGS .ply, plus the prepared input and the predicted camera - No CUDA, no conversion: it loads the original Idol weights (about 3.1 GB) directly - Same settings as the original: 50 steps and 262,144 Gaussians by default, adjustable from about 32K up to 1M - Photos or renders: a "real" mode for photos and a "synthetic" mode for renders and generated images - Local server: an /v1/meshes endpoint queues jobs and returns the PLY, if you want to call it from other tools The castle, factory and robot in the video were generated this way, at 50 steps and 262,144 splats each. You still need access to Meta's gated DINOv3 and the FLUX.2-dev VAE on Hugging Face. The output is a splat, not a mesh, so you'll need a splat viewer or a conversion step to use it as a regular model. github: Blaizzy/mlx-vlm
@_junaidkhalid1 @anitakirkovska Openbots? I just looked it up: this one? CopilotKit/OpenBot
How to build M3U playlist libraries for the Echo Mini Since FIIO has released 4.0.0 with M3U support and there has been community software like the EchoPod[[1]](reddit.com) which supports M3U & M3U8, I wonder what's the easiest way to build a playlist library over the tracks that you have on the Echo Mini?
Building a Production-Ready Financial & Quant Library in Python: Lessons from 100+ Scripts When building software for quantitative finance, banking analytics, or algorithmic trading, there's often a temptation to over-engineer. We pull in massive, heavy frameworks when all we really need is clean, modular, and dependency-light Python code. Over the past few months, I set out to solve this exact problem by building and curating a comprehensive repository of 100+ standalone, copy-paste ready Python scripts spanning core banking, credit risk scoring, quantitative risk metrics, and technical indicators. 🌐 Live Library: PyQuant Library 📦 GitHub Master Index: Awesome Python Quant Scripts --- Why Focus on Standalone Scripts? Most quants, developers, and financial analysts don't want a monolithic framework that takes hours to configure. They need modular code that can be dropped directly into Jupyter Notebooks, automated trading bots, or internal banking dashboards. By sticking to standard, robust libraries (pandas, numpy, scipy, yfinance), these scripts remain fast, transparent, and easy to audit. --- Core Modules Covered in the Library 1. Core Banking & Credit Risk Modeling In traditional banking and lending, having quick access to core calculation scripts saves hours of spreadsheet chaos. The library includes: - Credit Risk Scoring & Probability of Default (PD) Models (Basel-aligned expected loss frameworks) - Corporate Credit Appraisal & Financial Ratio Calculators (DSCR, ICR, Leverage) - Loan Amortization & Prepayment Cashflow Engines - NPA & Delinquency Bucket Migration (DPD) Trackers 2. Quantitative Finance & Portfolio Risk For portfolio managers and quants looking to measure tail risk and optimize allocations: - Markowitz Portfolio Optimization & Efficient Frontier - Value at Risk (VaR) & Expected Shortfall - Monte Carlo Stock Price & Portfolio Simulations - Option Pricing & Greeks (Black-Scholes bisection solvers) 3. Technical Indicators & Algo-Trading Signals Clean calculation scripts for trend, momentum, and volatility: - Supertrend & ATR Trailing Stop Confluence - 200/50 EMA Trend Filters & Crossovers - Intraday VWAP & Anchor VWAP Calculators - Bollinger Band Squeeze Breakout Scanners --- Check Out the Complete Collection Every single script in the library is 100% free to read, copy, and adapt for your own projects. - Browse all 101 pages live: pyquant-library.netlify.app - Explore code & star the repo: GitHub Repository If you're building financial tools or trading automation in Python, check it out and let me know what scripts you'd like to see added next!
Repo (Apache-2.0): Anil-matcha/open-duet Needs Node.js 22+ and uv: git clone Anil-matcha/open-duet cd open-duet/desktop npm run app Still early, so expect bugs. Bring your own model/API key.
Live Voice Changer for Discord, games, and etc You know, I’ve always had a problem finding a proper voice changer for games, Discord, etc. They were either too complex, pricy, or hard to find and set up. I wanted something simple that would work with one click, so I built one myself. iamjorj/voxel Would love to hear your feedback.
#Qt6 #MarkdownEditor #viMarkdown ver 0.3.209 beta版をリリースだん。 github.com/vivisuke/viMarkdown/releases/tag/v0.3.…